There’s a world
beneath the
interface.
I reverse-engineer APIs and build scalable scrapers.
Python, Playwright, async pipelines.
Protocol study
Forward thinking. Scroll to discover
Under the surface.
Open-source packages and Apify actors I build / 2026Google Maps,
decoded.
GoogleMapsCollector reverse-engineers Google Maps’ internal protobuf API: grid search over any area, dedup by place_id and hex_id, async streaming, checkpoints and adaptive rate limiting.
On the Apify Store it runs as Google Maps Scraper: business listings with reviews, hours and GPS, plus optional emails, socials, contacts and ad intelligence. Pay per event.
Explore the recorded runOn the Apify Store
Nine public actors I publish / pay per eventOpen-source packages
On GitHub and PyPI-
Meta Ad Library ads through a CLI, a Python API, or an MCP server for AI assistants. No Meta API key. Search, inspect, export JSON, JSONL or CSV, and watch for newly observed ads.
Repository for MetaAdsCollector -
Secretary-of-State business registrations and professional licenses. HTTP first, with a Playwright and Camoufox fallback; 23 states working.
Repository for gov_websites_collector -
LLM-powered structured extraction over crawl4ai: define fields in plain English, point at a URL, get typed data. Batch and full-site crawl.
Repository for generic-scraper-1 -
A URL becomes a structured site profile in two HTTP requests: stack, CDN, anti-bot vendor, captcha, framework, structured data, robots and a first-guess extraction strategy. 30+ detectors, MCP server.
Repository for site-profiler -
LinkedIn profile extraction with anti-detection, cookie management and multi-instance search.
Repository for linkedin-profile-extractor -
Decoder for Google Maps protobuf parameters; a research utility.
Repository for google-maps-pb-decoder -
Search for publicly accessible files (Docs, Drive, PDFs, spreadsheets) across the web.
Repository for open_files -
Open-source AI browser agent for Chrome and Firefox.
Repository for webbrain -
Self-hosted AI marketing department: a CMO agent delegating to specialists; approval-first, file-based, on OpenClaw.
Repository for marketingclaw
Star counts: GitHub, fetched 2026-10-29.
Reverse-engineer a site.
Enter a public page. A real browser loads it, records its network traffic and visible content, and ranks the responses most likely to contain the data behind the page.
The analyzer runs a real browser on a server. Here the page plays one recorded capture of a fictional site.
Showing the sample for northgate-trades.example. The real analyzer runs a browser on a server; this page fetches nothing.
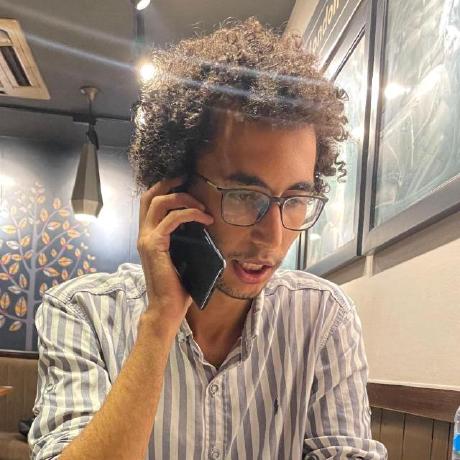
About me. I’m Youssef Nagy.
يوسف جمال يوسف محمد ناجي
I live and work in Arish, on the Mediterranean coast of Sinai. I’m a web scraping and data extraction engineer: I specialize in reverse-engineering closed APIs (protobuf, GraphQL, internal endpoints) and turning them into clean, scalable data pipelines.
Where I can, I decode the underlying protocol and extract over plain HTTP instead of driving a browser; where a source needs one, I use Playwright or Camoufox.
I publish what I build: the open-source pip packages gmaps-extractor, meta-ads-collector and gov-websites-collector, the public actors on my Apify Store page, and the reverse-engineering lab further up this page, which I built for this site.
I work in Arabic and English.
How I got here
On GitHub since July 2017. My repositories tell the rest: from driving browsers to reading the wire protocol directly.
- JavaScript scraping experiments.
- Selenium scrapers with anti-detection, and an Amazon scraper.
- A browser-automation Google Maps scraper, open_files, and an LLM-driven scraper.
- The reverse-engineered collectors: GoogleMapsCollector and MetaAdsCollector.
- generic-scraper-1 and gov_websites_collector.
- site-profiler.
- marketingclaw and webbrain.
- Nine public actors on the Apify Store.
What I read
Beyond my own work, I follow typed functional programming (Scala, ZIO), durable computing (Rust, golem), offensive-security tooling (nuclei, subfinder, tlsx), and AI agents and crawlers (browser-use, crawl4ai).
Understand the system.
Then make it useful.
What I do
- API reverse engineeringPrivate protocols (protobuf, GraphQL, internal REST) decoded for direct HTTP extraction without a browser.
- Anti-bot workTLS fingerprinting, anti-detect browsers such as Camoufox, ISP and residential proxies, against Cloudflare, Shape Security, Incapsula and DataDome.
- Scalable pipelinesAsync collection, proxy rotation, checkpoint resumption, deduplication and streaming output.
- Open-source toolingpip packages with CLIs, streaming APIs, event systems and MCP servers.
- Government and public dataBusiness registrations and professional licenses from 23 US state portals.
Tech stack
- Languages
- Python, JavaScript, TypeScript
- Scraping
- Playwright, Selenium, Scrapy, aiohttp, httpx, Camoufox
- Reverse engineering
- Protobuf, GraphQL, TLS fingerprinting, HTTP/2
- Backend
- FastAPI, Node.js, React
- Databases
- PostgreSQL, MongoDB, Redis
- Infrastructure
- Docker, proxy rotation, ISP proxies, Apify platform
Working with me
I’m one engineer, available for custom work. When you write to me, you talk to the person who writes the code. If you need data from a source none of my tools cover yet, I build custom extraction systems for it: send me the source and the fields you need, by email or on LinkedIn.
If you would rather run it yourself, my actors on the Apify Store are pay per event, and the pip packages install in one line.